Free Demo


Enough for tests after 20 or 30 hours' practices
You must have known the exciting feeling when it may take others several months or even several years to pass the exam but you need only 20 or 30 hours to pass the exam easily with our Associate-Developer-Apache-Spark-3.5 dumps torrent: Databricks Certified Associate Developer for Apache Spark 3.5 - Python. Now, under the guidance of our Associate-Developer-Apache-Spark-3.5 real questions, you can experience such feeling by yourself. Without sitting in front of the desk all day long to prepare for the coming exam, you only need to look through our Associate-Developer-Apache-Spark-3.5 latest dumps and do exercise in your spare time, you can easily get the hang of the key points which are going to be tested in the real exam. As a result, when it comes to the questions of the same difficulty, you may just need a quarter of total time used by others who don't use our Associate-Developer-Apache-Spark-3.5 training materials: Databricks Certified Associate Developer for Apache Spark 3.5 - Python.
Pre-trying experience
Compared with other exam learning material files, our Associate-Developer-Apache-Spark-3.5 dumps torrent: Databricks Certified Associate Developer for Apache Spark 3.5 - Python can provide you with per-trying experience, which is designed to let you have a deep understanding about the exam files you are going to buy. The reason why our Associate-Developer-Apache-Spark-3.5 training online materials are confident to receive pre-trying check is that they are highly qualified and suitable for all kinds of people as they are possessed of three different versions for people to choose from. What's more, the majority of population who has had the pre-trying experience finally choose to buy our Associate-Developer-Apache-Spark-3.5 training materials: Databricks Certified Associate Developer for Apache Spark 3.5 - Python as people all deem our exam files as the most befitting study materials.
As an old saying goes, once bitten, twice shy, with so many awful experiences with those inferior exam files, aren't you afraid to try them again? If you answer is yes, I believe I can help you out of the awkward situation. My suggestion is that you can try to opt to our Associate-Developer-Apache-Spark-3.5 dumps torrent: Databricks Certified Associate Developer for Apache Spark 3.5 - Python. By choosing our exam study materials, you will never have to worry about your exam grades because you can be the top one easily. Here are striking points of our Associate-Developer-Apache-Spark-3.5 real questions.
Many benefits for the PDF version
If you choose the PDF version of our Associate-Developer-Apache-Spark-3.5 real questions, you will have access to the free download of demo so that you can enjoy the pre-trying experience. In this way, you can have a good understanding of our Associate-Developer-Apache-Spark-3.5 dumps torrent: Databricks Certified Associate Developer for Apache Spark 3.5 - Python and decide whether to buy or not. What's more, the PDF version of our Associate-Developer-Apache-Spark-3.5 training online materials can be printed into paper version so as to provide you with much convenience to underline the important knowledge points and sentences. In this way, the second time you pick up your paper, you can know clearly which parts to recite and which just have to cast glances. Not only will it save a large amount of time for you, but also improve your learning efficiency.
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Using Pandas API on Spark | 5% | - Pandas API
|
| Topic 2: Structured Streaming | 10% | - Streaming Applications
|
| Topic 3: Using Spark SQL | 20% | - Spark SQL Operations
|
| Topic 4: Troubleshooting and Tuning | 10% | - Performance Optimization
|
| Topic 5: Apache Spark Architecture and Components | 20% | - Spark Architecture
|
| Topic 6: Using Spark Connect to Deploy Applications | 5% | - Spark Connect
|
| Topic 7: Developing Apache Spark DataFrame API Applications | 30% | - DataFrame Operations
|
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
A data engineer observes that an upstream streaming source sends duplicate records, where duplicates share the same key and have at most a 30-minute difference in event_timestamp. The engineer adds:
dropDuplicatesWithinWatermark("event_timestamp", "30 minutes")
What is the result?
- A. It accepts watermarks in seconds and the code results in an error
- B. It removes duplicates that arrive within the 30-minute window specified by the watermark
- C. It removes all duplicates regardless of when they arrive
- D. It is not able to handle deduplication in this scenario
Correct Answer: B 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
Which configuration can be enabled to optimize the conversion between Pandas and PySpark DataFrames using Apache Arrow?
- A. spark.conf.set("spark.pandas.arrow.enabled", "true")
- B. spark.conf.set("spark.sql.execution.arrow.enabled", "true")
- C. spark.conf.set("spark.sql.execution.arrow.pyspark.enabled", "true")
- D. spark.conf.set("spark.sql.arrow.pandas.enabled", "true")
Correct Answer: C 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
37 of 55.
A data scientist is working with a Spark DataFrame called customerDF that contains customer information.
The DataFrame has a column named email with customer email addresses.
The data scientist needs to split this column into username and domain parts.
Which code snippet splits the email column into username and domain columns?
- A. customerDF = customerDF \
.withColumn("username", split(col("email"), "@").getItem(0)) \
.withColumn("domain", split(col("email"), "@").getItem(1)) - B. customerDF = customerDF.withColumn("username", regexp_replace(col("email"), "@", ""))
- C. customerDF = customerDF.withColumn("domain", col("email").split("@")[1])
- D. customerDF = customerDF.select("email").alias("username", "domain")
Correct Answer: A 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
Given the schema: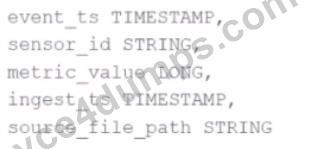
event_ts TIMESTAMP,
sensor_id STRING,
metric_value LONG,
ingest_ts TIMESTAMP,
source_file_path STRING
The goal is to deduplicate based on: event_ts, sensor_id, and metric_value.
Options:
- A. groupBy without aggregation (invalid use)
- B. dropDuplicates with no arguments (removes based on all columns)
- C. dropDuplicates on the exact matching fields
- D. dropDuplicates on all columns (wrong criteria)
Correct Answer: C 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).
The following code fragment results in an error:
@F.udf(T.IntegerType())
def simple_udf(t: str) -> str:
return answer * 3.14159
Which code fragment should be used instead?
- A. @F.udf(T.DoubleType())
def simple_udf(t: float) -> float:
return t * 3.14159 - B. @F.udf(T.IntegerType())
def simple_udf(t: float) -> float:
return t * 3.14159 - C. @F.udf(T.DoubleType())
def simple_udf(t: int) -> int:
return t * 3.14159 - D. @F.udf(T.IntegerType())
def simple_udf(t: int) -> int:
return t * 3.14159
Correct Answer: A 🗳️
Explanation: Only visible for VCE4Dumps members. You can sign-up / login (it's free).